asyncio is Python’s built-in library for running many waiting operations at once, so your program can fetch ten web pages in roughly the time it takes to fetch one. asyncio explained with simple examples comes down to four ideas: an event loop that schedules work, coroutines that can pause, tasks that start coroutines, and await, the keyword that hands control back while something else runs.
The shortest useful program is five lines, and the output proves the point better than any paragraph does.
import asyncio

async def main():
    await asyncio.sleep(1)
    print("done")

asyncio.run(main())
That script prints done after roughly one second. Swap asyncio.sleep(1) for time.sleep(1) and you get the same output, but now nothing else can run during that second. That single difference is what this guide unpacks, with runnable examples you can paste straight into a file.
Table of Contents
- What Is asyncio and What Problem Does It Solve?
- The Core asyncio Concepts You Need First
- How Does the asyncio Event Loop Work?
- How to Write and Run Your First Async Python Function
- Why do I get ‘coroutine was never awaited’?
- async def, await, and Coroutines: asyncio Explained with Simple Examples
- Why Do You Need asyncio Tasks?
- How to Run Multiple Async Operations Concurrently
- How to Manage Timeouts, Cancellation, and Cleanup
- How to Handle Exceptions in Async Code
- Async Sleep, Files, and Network Requests: What Is Actually Concurrent?
- Common asyncio Mistakes and How to Fix Them
- 1. Forgetting to await a coroutine
- 2. Calling time.sleep, requests.get, or a big open().read() inside a coroutine
- 3. Creating tasks without keeping a reference
- 4. Fire-and-forget tasks with no error handling
- 5. Expecting a speed-up on CPU-bound work
- 6. Leaving resources unclosed on the error path
- Frequently Asked Questions
- Is asyncio the same as multithreading?
- What is the difference between await and asyncio.sleep?
- When should I use asyncio.gather instead of asyncio.wait?
- Can I use requests or time.sleep inside asyncio code?
- How do I run an async function from an existing Python program?
- Is asyncio useful for CPU-intensive work?
- Conclusion
What Is asyncio and What Problem Does It Solve?
asyncio is a standard-library framework for writing concurrent programs with the async def and await keywords. It overlaps the time your program spends waiting on the network, disk, or database, so one thread can juggle thousands of pending operations instead of handling them one after another.
Concurrency and parallelism are not the same thing, and mixing them up is the most common confusion I see. Concurrency means making progress on several tasks in overlapping time, even if only one instruction runs at any instant. Parallelism means literally running instructions at the same instant on several cores.
asyncio gives you concurrency without parallelism. Your program stays single-threaded, and it never gets faster at crunching numbers. It gets faster at waiting.
If your program spends most of its life blocked on the network, asyncio is a good fit. If it spends its life burning CPU, it is the wrong tool, and no amount of await will change that.
| Approach | Best for | Runs work at the same time on | Memory cost per unit | Watch out for |
|---|---|---|---|---|
| asyncio | Thousands of network or database waits | One thread, overlapping I/O | Very low | Any blocking call freezes everything |
| threading | Blocking library calls, moderate concurrency | Many threads, one core or more | Moderate | Shared state, GIL limits CPU work |
| multiprocessing | CPU-heavy number crunching | Separate processes with real cores | High | Pickling data across process boundaries |
That table is the answer to the question that shows up most often on Stack Overflow and r/learnpython: pick asyncio for concurrent I/O, threads for concurrent blocking work, and processes for concurrent CPU work. You can mix them, and later in this guide you will see how to call blocking code safely from inside a coroutine.
The Core asyncio Concepts You Need First
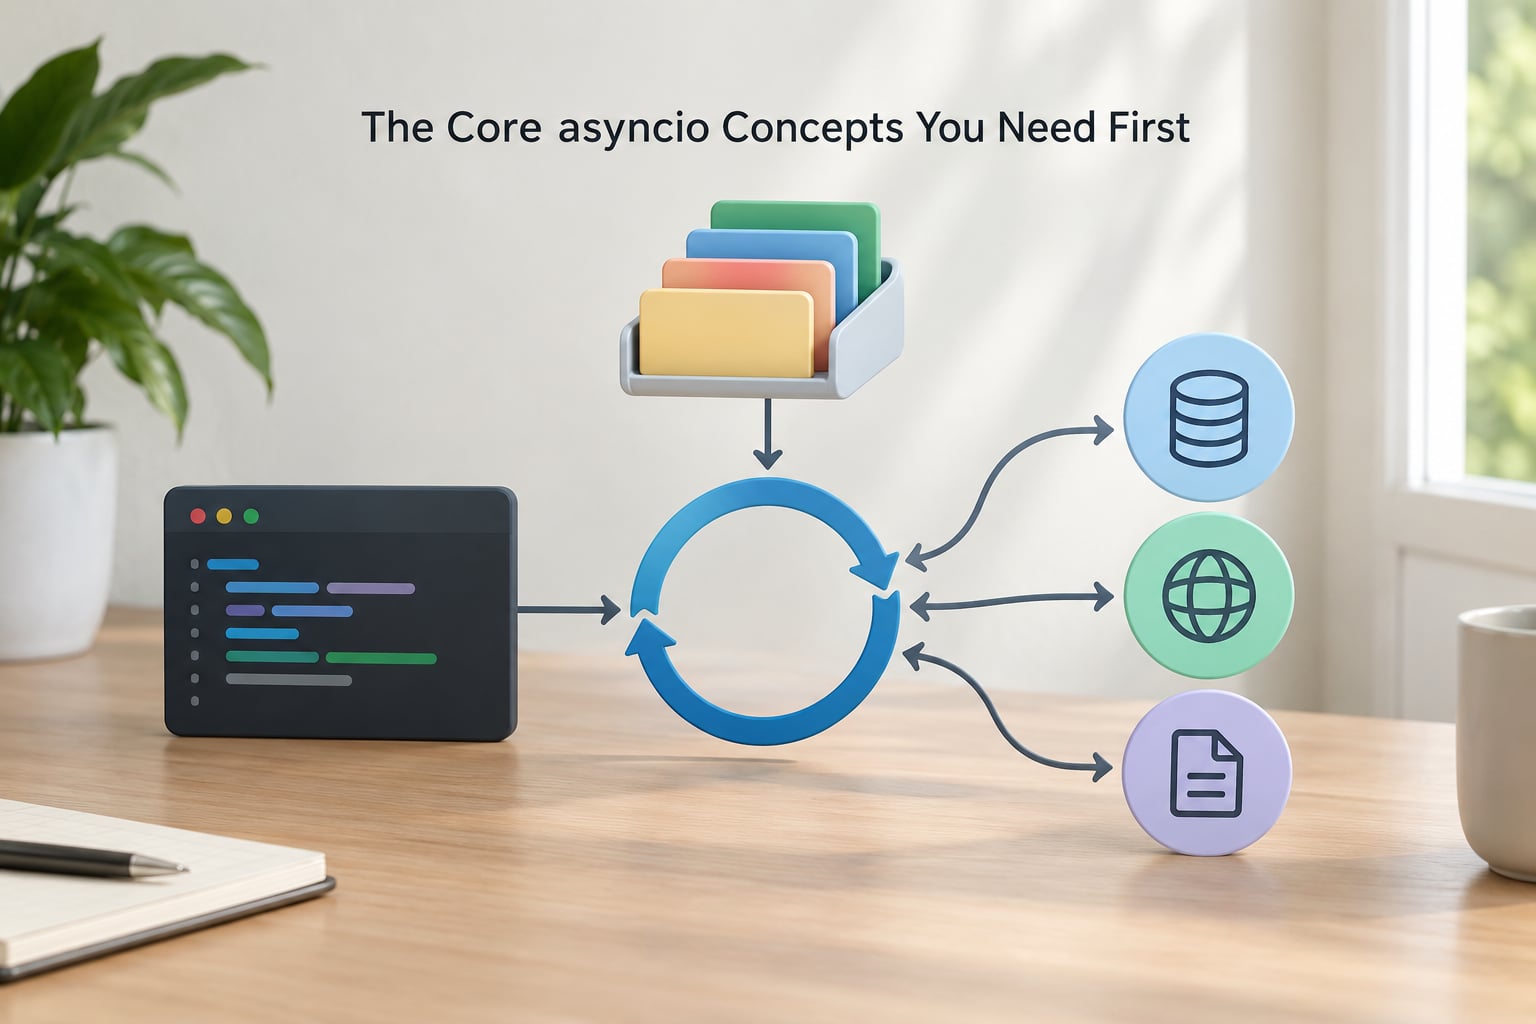
Four words show up in every asyncio tutorial. Getting them straight early saves a lot of confusion later.
| Concept | What it actually is | Created by |
|---|---|---|
| Coroutine | A function that can pause and resume. Calling it does nothing yet | Writing async def |
| Task | A coroutine that has been scheduled on the loop and can run on its own | asyncio.create_task() |
| Future | A placeholder for a result nobody has computed yet | The event loop, or libraries you use |
| Awaitable | The umbrella term for anything you can put after await | Coroutines, tasks and futures all qualify |
Here is how they connect in about eight lines. The task runs, hits await, and the loop keeps going.
import asyncio

async def work(name):
    print(f"{name} started")
    await asyncio.sleep(1)
    print(f"{name} finished")
    return name

async def main():
    coro = work("job")          # a coroutine, not running yet
    task = asyncio.create_task(coro)   # now the loop owns it
    print("main is free while job waits")
    result = await task
    print("got back:", result)

asyncio.run(main())
Console output, in this order:
main is free while job waits
job started
job finished
got back: job
The line printed before job started is the giveaway. The main coroutine kept going while work was suspended, which is exactly the behaviour that is impossible with ordinary blocking calls.
How Does the asyncio Event Loop Work?
The event loop is the scheduler that makes single-threaded concurrency possible. It is a simple repeating cycle, and you never have to drive it yourself because asyncio.run does that for you.
Each pass through the loop does roughly three things. It runs every callback that is ready right now, then asks the operating system which network or file operations have completed, then it blocks briefly waiting for one of them to finish.
When a coroutine hits await on an operation that is not ready, it suspends. The loop removes it from the ready set and moves on to the next coroutine that is ready. Later, when the socket has data, the loop marks that coroutine ready and resumes it at exactly the line where it left off.
Nothing preempts your code. A coroutine only gives up the thread at an await, which is why the loop is described as cooperative multitasking. A single long chunk of plain Python with no await inside it holds the thread until it finishes.
The practical consequence is that await points are your only tool for sharing the thread. If you want two operations to overlap, you need to be awaiting them separately or running them as tasks, and that is the whole subject of the next few sections.
How to Write and Run Your First Async Python Function
You need three things to run async code: an async def function, an await somewhere inside it, and asyncio.run to start the loop. Miss any one and nothing happens.
import asyncio

async def fetch():
    await asyncio.sleep(0.5)
    return "response body"

async def main():
    body = await fetch()
    print(body)

if __name__ == "__main__":
    asyncio.run(main())
The async def keyword does not run the function. It wraps the body in a coroutine object and hands it back to you. The await keyword runs that coroutine and pauses at the point where the result is needed.
asyncio.run creates an event loop, runs your main coroutine until it finishes, then closes the loop. It is the modern entry point, and it is what you should use instead of the older asyncio.get_event_loop and loop.run_until_complete calls you will still find in tutorials published before 2020.
Why do I get ‘coroutine was never awaited’?
Because you created a coroutine and threw it away. Calling an async function without awaiting it does not run any of its code.
import asyncio

async def main():
    print("hello")

asyncio.run(main())       # fine

async def other():
    print("never printed")

other()                    # creates a coroutine, drops it
Python prints a RuntimeWarning along the lines of coroutine ‘other’ was never awaited. It is only a warning, which is exactly why it confuses people: the program does not crash, so the missing work goes unnoticed until someone notices the missing output.
The fix is to await it, wrap it in a task with asyncio.create_task, or collect it with asyncio.gather. Any of the three makes it real.
async def, await, and Coroutines: asyncio Explained with Simple Examples
A coroutine is just a function that knows how to pause. Watch what happens when you await two sleeping coroutines one after the other.
import asyncio

async def slow():
    await asyncio.sleep(1)
    return "slow"

async def medium():
    await asyncio.sleep(2)
    return "medium"

async def main():
    a = await slow()
    b = await medium()
    print(a, b)

asyncio.run(main())
This takes about three seconds, not one. The first await blocks the whole coroutine until slow returns, and medium does not even start until then. Sequential awaits are sequential.
Now compare that with scheduling them independently:
import asyncio

async def slow():
    await asyncio.sleep(1)
    return "slow"

async def medium():
    await asyncio.sleep(2)
    return "medium"

async def main():
    results = await asyncio.gather(slow(), medium())
    print(results)

asyncio.run(main())
Same two functions, about two seconds instead of three. Both sleep timers are in flight at once, and gather waits for both and returns the results in the order you passed them.
That is the entire idea behind asyncio in one example. Not faster work, just overlapping waits.
Why Do You Need asyncio Tasks?
A task is a coroutine the event loop has taken responsibility for. Once something is a task, it can run and suspend on its own while your main coroutine does something else.
import asyncio

async def worker(n):
    await asyncio.sleep(n)
    return f"worker {n} done"

async def main():
    tasks = [asyncio.create_task(worker(n)) for n in (3, 1, 2)]

    for task in tasks:
        print("started:", task.get_name(), "| done:", task.done())

    done, pending = await asyncio.wait(tasks)
    for t in sorted(done, key=lambda x: x.result()):
        print("finished:", t.result())

asyncio.run(main())
The started lines all print False for done, because create_task schedules the work but nothing has had a chance to run yet. Then asyncio.wait splits the set into finished and still-running work, and the results come back ordered by how quickly each worker slept.
asyncio.wait never cancels anything and never raises task exceptions, which makes it a good tool when you want to inspect results yourself.
Keep a reference to every task you create. asyncio holds only a weak reference, so a task with no variable pointing at it can be garbage-collected mid-flight and quietly disappear. Saving them in a list or a set fixes it, and that habit is worth forming on day one.
How to Run Multiple Async Operations Concurrently
Unbounded concurrency is a trap. Fire off ten thousand requests at once and you get ten thousand sockets, a rate-limit response, or an out-of-memory error.
An asyncio.Semaphore caps how many coroutines may be inside a block at any moment. The rest queue up politely.
import asyncio

async def fetch(url, sem):
    async with sem:
        await asyncio.sleep(0.5)
        return f"{url} -> 200"

async def main():
    sem = asyncio.Semaphore(5)
    urls = [f"https://api.example.com/item/{i}" for i in range(20)]
    results = await asyncio.gather(*(fetch(u, sem) for u in urls))
    print(len(results), "done")

asyncio.run(main())
Twenty fetches at half a second each would take ten seconds if run one after another. With a limit of five, it takes about two seconds, and the process never has more than five connections open.
Pick a limit that reflects the service on the other end. A public API might publish a rate limit; a database connection pool usually has a fixed size you can match. The same semaphore idea appears in asyncio.Queue for producer and consumer pipelines and in asyncio.Lock for protecting shared state.
How to Manage Timeouts, Cancellation, and Cleanup
Without a timeout, one slow request can hang your program forever. asyncio.timeout is the current way to bound a block of code, and asyncio.wait_for is the older one-shot form that still works everywhere.
import asyncio

async def flaky():
    await asyncio.sleep(10)
    return "never gets here"

async def main():
    try:
        async with asyncio.timeout(1):
            await flaky()
    except TimeoutError:
        print("gave up after 1 second")

asyncio.run(main())
On Python 3.10 and older, use await asyncio.wait_for(flaky(), timeout=1) and catch asyncio.TimeoutError.
What happens on timeout is worth understanding, because it drives your cleanup code. The loop raises CancelledError inside the coroutine at its current await point. That exception unwinds the stack, so a try/finally block runs and your connection or file handle gets closed.
import asyncio

async def fetch_with_cleanup(sem):
    async with sem:
        try:
            await asyncio.sleep(5)
        finally:
            print("releasing the slot")

async def main():
    sem = asyncio.Semaphore(1)
    task = asyncio.create_task(fetch_with_cleanup(sem))
    await asyncio.sleep(0.2)
    task.cancel()
    try:
        await task
    except asyncio.CancelledError:
        print("task was cancelled cleanly")

asyncio.run(main())
Put cleanup in finally, never after the await that may fail, and the resource is released whether the call succeeds, times out, or is cancelled. An async with block on a client library gives you the same guarantee for free, which is why it is worth preferring over manual close calls.
How to Handle Exceptions in Async Code
Errors in async code follow the same rules as normal code in one respect: an exception inside a coroutine propagates to whoever is awaiting it. The difference is how it behaves when several coroutines run at once.
import asyncio

async def ok(n):
    await asyncio.sleep(0.2)
    return f"ok {n}"

async def bad(n):
    await asyncio.sleep(0.2)
    raise ValueError(f"item {n} exploded")

async def main():
    try:
        results = await asyncio.gather(ok(1), bad(2), ok(3))
        print(results)
    except ValueError as exc:
        print("caught:", exc)

asyncio.run(main())
gather is fail-fast by default. The ValueError surfaces as soon as it happens, and asyncio.run then cancels the sibling tasks that are still running. The first line printed is caught: item 2 exploded.
When you would rather collect every result and deal with failures afterwards, pass return_exceptions=True:
    results = await asyncio.gather(
        ok(1), bad(2), ok(3), return_exceptions=True
    )
    for r in results:
        if isinstance(r, Exception):
            print("failed:", r)
        else:
            print("succeeded:", r)
Now the two successful calls report in and the failed one comes back as a ValueError object instead of being raised. For batch work where one missing record should not kill the run, this is usually what you want.
On Python 3.11 and newer, asyncio.TaskGroup gives you a cleaner model. Tasks live inside a with block, one failure cancels the rest, and the group raises an ExceptionGroup so you see every error rather than just the first.
Async Sleep, Files, and Network Requests: What Is Actually Concurrent?
asyncio.sleep yields the thread so other work runs. time.sleep does not, which makes it the perfect illustration of what not to do.
import asyncio, time

async def bad():
    time.sleep(1)
    print("blocking call finished")

async def good():
    await asyncio.sleep(1)
    print("non-blocking wait finished")

async def main():
    start = time.perf_counter()
    await bad()
    print(f"{time.perf_counter() - start:.1f}s")

asyncio.run(main())
This prints roughly 1.0s. While the blocking call ran, the loop could do nothing at all, even if you had a hundred other coroutines ready.
The same applies to file operations. The built-in open and read are blocking, so reading a big file inside a coroutine stalls everything else. Wrap them with asyncio.to_thread, which hands the blocking call to a worker thread and gets control back immediately.
import asyncio, pathlib

async def main():
    data = await asyncio.to_thread(pathlib.Path("notes.txt").read_text)
    print(len(data), "characters")

asyncio.run(main())
await loop.run_in_executor(None, blocking_function, arg)run_in_executor is the older, lower-level version of the same idea. to_thread arrived in Python 3.9 and handles the argument passing for you, so reach for it first.
For HTTP, use an async client. httpx and aiohttp both offer async APIs where one client object handles many requests efficiently.
import asyncio, httpx

async def get(client, url):
    r = await client.get(url, timeout=5.0)
    return r.status_code

async def main():
    urls = ["https://example.com", "https://example.org"]
    async with httpx.AsyncClient() as client:
        codes = await asyncio.gather(*(get(client, u) for u in urls))
    print(codes)

asyncio.run(main())
The async context manager closes the client and its connection pool when the block exits, including when a request raises. If you use the requests library instead, every call inside blocks the loop until the response lands, and you lose the overlap entirely.
For databases, look for an async driver such as asyncpg or SQLAlchemy’s AsyncSession rather than wrapping a synchronous driver in to_thread. The first option keeps everything on one event loop and avoids thread-safety surprises.
Common asyncio Mistakes and How to Fix Them
These six come up over and over, and most of the confusion on r/learnpython traces back to one of them.
1. Forgetting to await a coroutine
The coroutine object is created and dropped, and you get a RuntimeWarning about a coroutine that was never awaited, or silently missing output. Fix: await it, or hand it to create_task or gather.
2. Calling time.sleep, requests.get, or a big open().read() inside a coroutine
Any synchronous call holds the thread until it returns, so every other coroutine waits with it. Fix: await asyncio.sleep for waits, an async client for HTTP, and asyncio.to_thread for blocking work you cannot replace.
3. Creating tasks without keeping a reference
asyncio keeps only a weak reference, so a task with no variable pointing at it may be collected before it finishes. Fix: store tasks in a list or set, or use a TaskGroup where lifetime is managed for you.
4. Fire-and-forget tasks with no error handling
A task that raises nobody awaits, so the exception vanishes. Fix: await the task, or add a done callback that logs task.exception().
task = asyncio.create_task(risky())
task.add_done_callback(lambda t: print("failed:", t.exception()))
5. Expecting a speed-up on CPU-bound work
Async code still runs on one thread, so number crunching takes exactly as long as before. It overlaps waiting only. Fix: use a process pool or multiprocessing for CPU work, and asyncio for I/O.
6. Leaving resources unclosed on the error path
A client or connection closed only on the happy path leaks when something raises. Fix: use async with, or put cleanup in a finally block so cancellation and exceptions release resources too.
One more habit worth adding: run your scripts with asyncio.run rather than get_event_loop. The older pattern still appears in most pre-2020 tutorials, and it misleads beginners about how the loop is created.
Frequently Asked Questions
Is asyncio the same as multithreading?
No. Multithreading runs several threads at once and the operating system can schedule them on different cores. asyncio runs coroutines on a single thread, switching between them only when one hits await. That makes asyncio much cheaper in memory and far easier to write correctly for I/O, while threads suit blocking library calls. Neither one speeds up CPU-bound work on its own.
What is the difference between await and asyncio.sleep?
await is a keyword that pauses the coroutine you are inside and lets the event loop run other work. asyncio.sleep is an async function that pauses for a given number of seconds. Using await time.sleep is a mistake because time.sleep blocks the whole thread. Use await asyncio.sleep to wait without freezing everything else in the program.
When should I use asyncio.gather instead of asyncio.wait?
Use gather when you want the results as a list, because it returns values in the order you passed the coroutines and propagates the first exception. Use wait when you care about which tasks finished rather than what they returned, because it splits tasks into done and pending sets and never raises task exceptions. For new code on Python 3.11 and later, TaskGroup covers much of the same ground with cleaner cancellation.
Can I use requests or time.sleep inside asyncio code?
Technically yes, but it defeats the purpose. Both are blocking, so the event loop cannot run any other coroutine until they return. For HTTP, use httpx.AsyncClient or aiohttp. For waiting, use asyncio.sleep. For blocking functions you cannot replace, wrap them with asyncio.to_thread so they run on a worker thread instead of stalling the loop.
How do I run an async function from an existing Python program?
Import asyncio and wrap the call in asyncio.run, which creates a loop, runs your coroutine to completion, and closes the loop afterwards. If your program already has a running loop, such as inside a web framework, you cannot call asyncio.run, and you schedule the coroutine with create_task or await it directly. In Jupyter, use await directly or nest inside asyncio.run.
Is asyncio useful for CPU-intensive work?
No. A single-threaded event loop cannot run two CPU operations at once, so number crunching and compression take exactly as long as synchronous code. asyncio is for I/O-bound programs that spend their time waiting on networks, disks, or databases. For CPU-heavy work, use multiprocessing or a process pool, and combine the two when a program does both.
Conclusion
asyncio explained with simple examples is really three habits: decide what you are waiting on, put those waits on separate tasks so they overlap, and never let a blocking call sit inside a coroutine.
Start by running the first snippet and then the gather version, then time both. Seeing one second become two is the moment it clicks for most people. After that, convert two independent operations in your own code into tasks and check the output.