An inode (index node) is a fixed-size record in a filesystem’s inode table that stores metadata about a file or directory: its type, size, owner, group, permissions, timestamps, link count and where its data blocks live. It never stores the filename, and it never stores the contents. If you take one idea from this guide, take that one, because almost every confusing inode question traces back to it.
That split is why a Linux filesystem can run out of room to create new files while still reporting gigabytes free. The two resources are counted separately, and this walkthrough shows you how to look at each one, starting with 2026-era tools that have not changed much since the early Unix days.
Table of Contents
- What Are Inodes in Linux?
- How Inode Numbers Work Across a Linux Filesystem
- What Metadata Does an Inode Store?
- Hard Links and Symbolic Links: How They Affect Inodes
- Hard links share one inode
- Symbolic links are their own inode holding a path
- How to Inspect Inode Information with Linux Commands
- Why Can’t I Create a File Even When Disk Space Is Available?
- How Inodes Behave When Files Are Deleted or Renamed
- Inodes, Blocks, and File Storage: Why They Are Not the Same
- How Filesystem Type Changes Inode Behavior
- Frequently Asked Questions
- What is an inode in Linux with an example?
- What happens when inodes are full?
- How do I check inode usage on Linux?
- How do I clean up inodes on Linux?
- Are hard links and filenames the same as inode numbers?
- Can I change inode numbers or increase inode count on a mounted filesystem?
- Conclusion: Start by Checking the Filesystem
What Are Inodes in Linux?
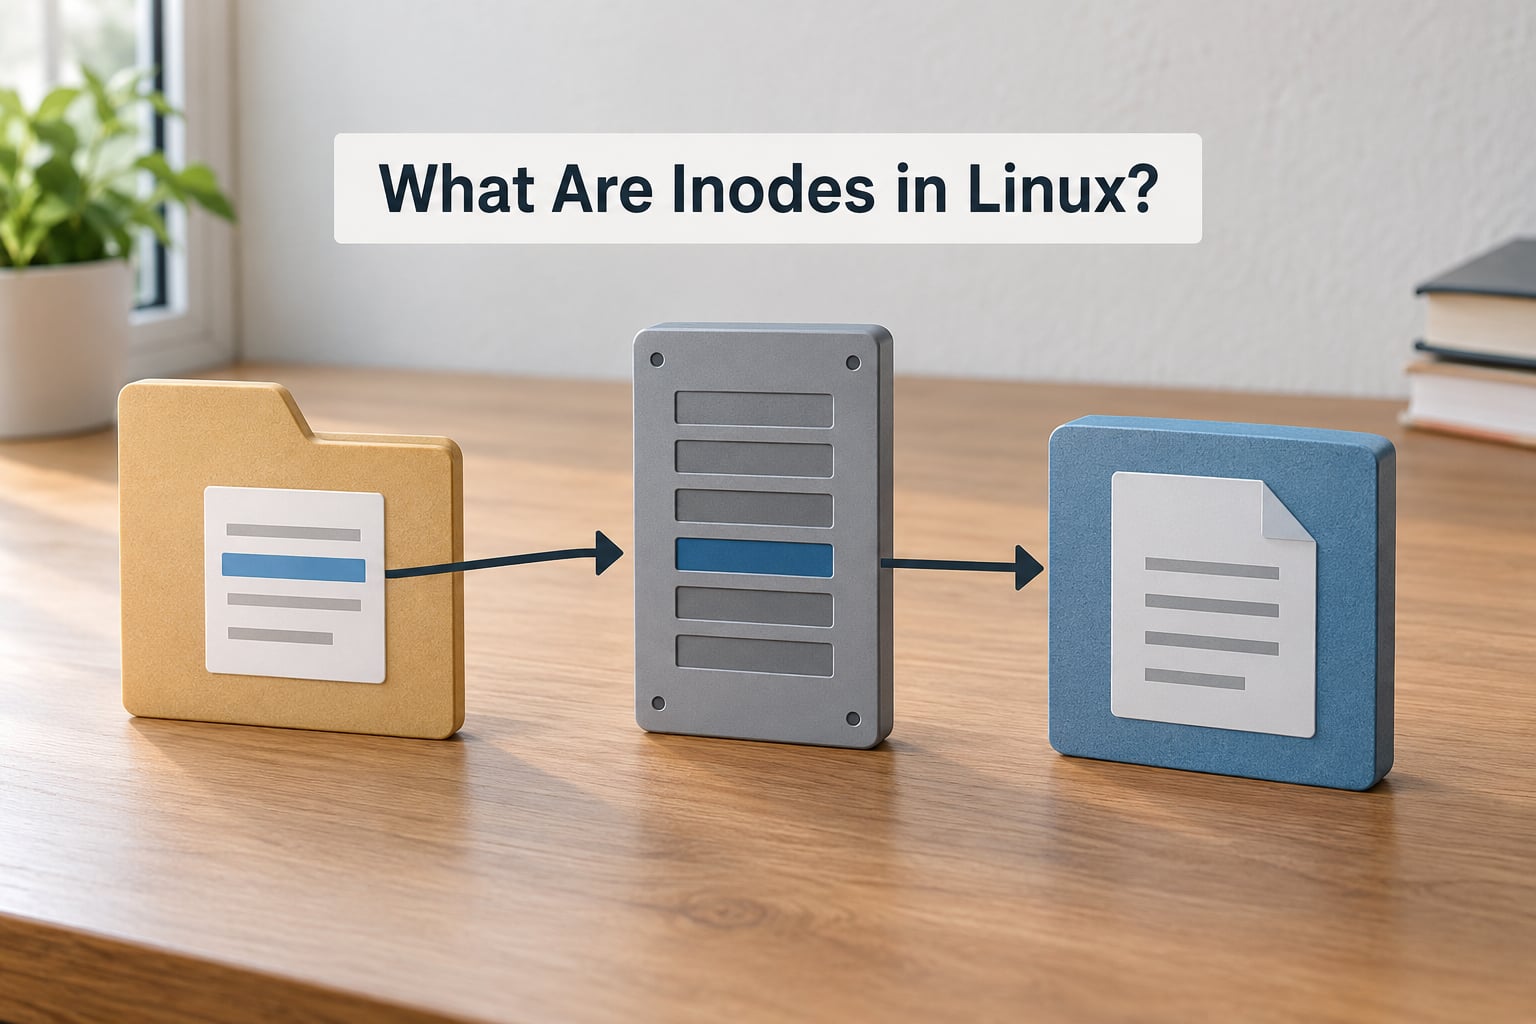
An inode is the filesystem’s bookkeeping record for one object. Think of a library: the catalogue card holds the author, the date, the shelf mark and where the book physically sits, while the book itself holds the words. The card is the inode. The words are the file data. And the call number someone wrote on the outside of the book, the filename, lives somewhere else entirely, in the directory.
Every file and every directory on an inode-based filesystem gets exactly one inode. Directories have inodes too, which surprises people: a directory is not just a list of names, it is an object with its own size, owner, permissions and block pointers.
| Thing | What it is | Where it lives | Contains the data? |
|---|---|---|---|
| Inode | Fixed-size metadata record with an inode number | Inode table inside the filesystem | No, only pointers to where data is |
| Filename | The name you type | Inside a directory entry | No |
| Directory entry | A name plus the inode number it maps to | Data blocks belonging to the parent directory | No |
| File data | The bytes you wrote | Allocated data blocks | Yes |
One consequence follows immediately: you can have ten names for one file and only one inode, and you can have a million files that are each one byte long. Those two situations look identical to a capacity check and behave completely differently on disk.
How Inode Numbers Work Across a Linux Filesystem
Inode numbers are assigned by the filesystem when a file is created, not by the kernel in any global sequence. When you create notes.txt in /home/ada/, the filesystem picks the next free slot in its inode table for that filesystem and returns the index of that slot. That index is the inode number, and ls -i shows it to you.
When you open a path like /var/log/syslog, the kernel walks the directory entries of /var, then log, then syslog, collecting inode numbers along the way. Once it reaches the final name, it looks that number up in the inode table, loads the record, and follows the block pointers inside it to read actual bytes. Names resolve to numbers; numbers resolve to records; records point at data.
Because the number is just an index into one filesystem’s table, it is only meaningful alongside that filesystem’s identity. A filesystem UUID plus an inode number is effectively unique across a machine. Copy the tree to another filesystem and the same file can easily land on a different number.
Copying and moving make the difference obvious. cp reads the source data and writes a brand new file, which means a brand new inode. mv within the same filesystem only rewrites a directory entry, so the inode number travels with the file. Move a file across filesystems and mv degrades into copy plus delete, so you get a new inode number anyway. This is the entire answer to the popular question of why inode numbers change after a copy but not after a move.
Three other terms get mixed up with inodes constantly, so here is the clean separation:
| Term | What it identifies | Scope | Where it exists |
|---|---|---|---|
| Inode | A file or directory on disk | Persistent, per filesystem | Inode table |
| Dentry (directory entry) | A name in a directory, mapped to an inode number | In-memory cache of names | Kernel dentry cache |
| Superblock | The filesystem itself: total size, free blocks, free inodes, mount state | One per mounted filesystem | On disk, mirrored in memory |
| File descriptor | An open handle a process holds, e.g. fd 3 | Per process, gone at exit | Process file table |
A file descriptor is the one beginners most often assume is the inode. It is not. Opening a file creates a new descriptor each time, and closing it does not touch the inode at all.
What Metadata Does an Inode Store?
The metadata list is short enough to memorise, and the mapping from stat output to inode fields is worth keeping open in a second terminal. Here is what a typical inode holds on an ext4 or XFS filesystem:
| stat output field | Inode field | Plain meaning |
|---|---|---|
| File type | i_mode (type bits) | Regular file, directory, symlink, device |
| Size | i_size | Bytes for a file, entries for a directory |
| Links | i_links_count | How many directory entries point here |
| Uid / Gid | i_uid / i_gid | Numeric owner and group, not names |
| Access / Modify / Change | i_atime, i_mtime, i_ctime | Last read, last write, last metadata change |
| Blocks | i_blocks | Space actually allocated, 512-byte units |
| Block pointers | i_block array | Direct, indirect and doubly indirect addresses of data |
What an inode does not store is just as important. The filename is in the directory, not the inode. Extended attributes, SELinux labels, POSIX ACLs and some capabilities live in separate structures that reference the inode rather than sitting inside the fixed-size record. That is one reason filesystems have separate commands for ACLs and attributes.
The exact field set also varies. XFS stores different information about large files than ext4, tmpfs keeps its records in RAM, and FAT-family filesystems have no inode at all in this sense. Reading stat output is still valid everywhere, but the meaning of a given field depends on the filesystem underneath.
Hard Links and Symbolic Links: How They Affect Inodes
Hard links share one inode
A hard link is a second directory entry pointing at the same inode number. ln creates one, and the link count in the inode goes up by one:
$ ls -li notes.txt
1310892 -rw-r--r-- 1 ada ada 812 Mar 4 09:12 notes.txt
$ ln notes.txt notes-copy.txt
$ ls -li notes.txt notes-copy.txt
1310892 -rw-r--r-- 2 ada ada 812 Mar 4 09:12 notes.txt
1310892 -rw-r--r-- 2 ada ada 812 Mar 4 09:12 notes-copy.txt
Same inode number, link count of 2. The link count only falls when a name is removed, and the inode itself is reclaimed when it reaches zero. A hard link cannot cross filesystems, since the new name would have to point into a different inode table.
This is the mechanism behind a backup pattern that trips people up. Hard-link snapshots built with cp -al or an rsync with hard links are cheap in bytes, but every one of those links is still a directory entry. The inode count on the volume climbs toward the limit while df -h shows the data as essentially free. Sysadmins running dated snapshot trees on backup servers describe exactly this pattern, where inode usage spikes sharply and byte usage barely moves.
Symbolic links are their own inode holding a path
A symbolic link is a small file with its own inode number whose contents are a pathname. It can point anywhere, including another filesystem or a location that does not exist yet:
$ ln -s /var/log/notes.log current.log
$ ls -li current.log
1310945 lrwxrwxrwx 1 ada ada 18 Mar 4 09:14 current.log
$ readlink current.log
/var/log/notes.log
Deleting a symbolic link removes only that name. The target is untouched. Deleting the target leaves the symlink dangling, which is why so many scripts check that a path exists before following it. The mode bits starting with l and link count of 1 are the quickest visual confirmation that you are looking at a symlink and not a regular file.
How to Inspect Inode Information with Linux Commands
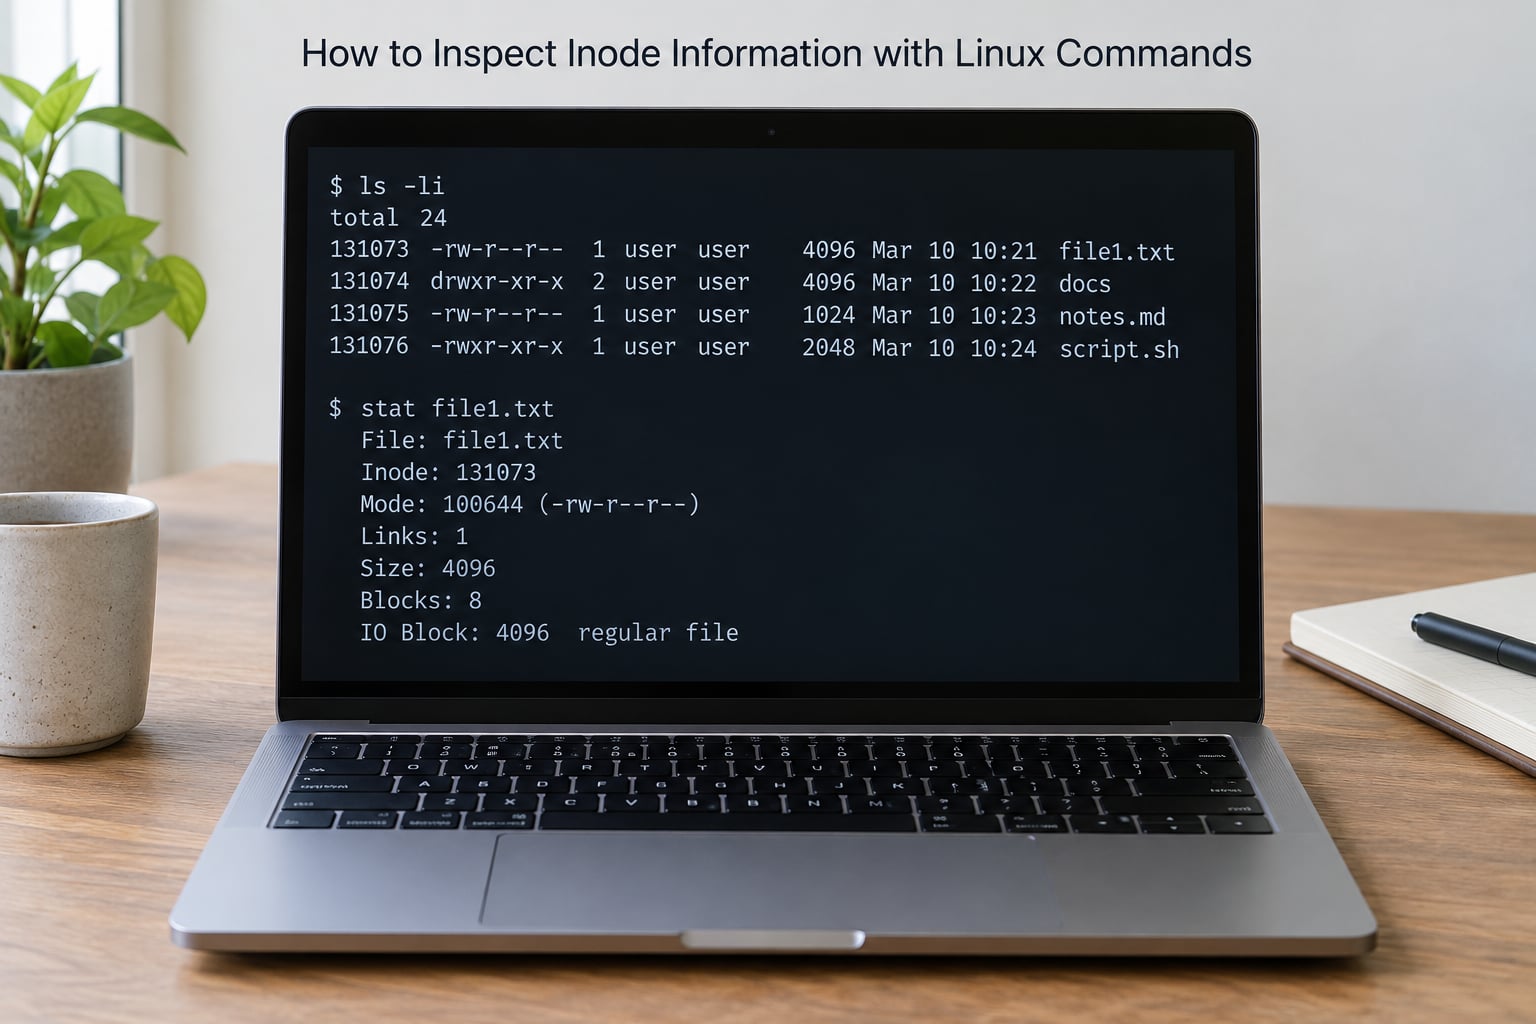
These commands assume a standard Linux shell with GNU coreutils and GNU findutils. BusyBox builds and non-GNU systems may support fewer flags, and macOS ships its own variants where stat takes different options.
To get a file’s inode number, ls -i prints the inode column in front of everything else:
$ ls -i /etc/hostname
1310743 /etc/hostname
To see permissions, link count, owner, size and inode together, add the long format with ls -li. For a directory itself rather than what is inside it, use the capital L so the listing describes the directory’s own inode:
$ ls -lid /var/log
1310811 drwxr-xr-x 25 root root 4096 Mar 4 09:20 /var/log
For full detail, stat is the tool. It prints fields most other commands hide, including the filesystem’s own view of blocks and the access time:
$ stat notes.txt
  File: notes.txt
  Size: 812       	Blocks: 8          IO Block: 4096   regular file
Device: 8,2   Inode: 1310892    Links: 2
Access: (0644/-rw-r--r--)  Uid: ( 1000/    ada)   Gid: ( 1000/    ada)
Access: 2026-03-04 09:12:44.101233456 +0000
Modify: 2026-03-04 09:12:41.887452100 +0000
Change: 2026-03-04 09:12:41.887452100 +0000
 Birth: 2026-02-28 14:03:09.220118774 +0000
To see how many inodes a whole filesystem is using, df -i is the one to memorise:
$ df -i /
Filesystem      Inodes  IUsed   IFree IUse% Mounted on
/dev/sda2      6553600 214882 6338718    4% /
Column by column: Inodes is the total the filesystem was created with, IUsed is how many are taken, IFree is what remains, and IUse% is the percentage consumed. That fourth column is the one to watch in monitoring, and it is completely separate from the Use% column in df -h, which measures bytes.
Run df -h and df -i next to each other whenever a write fails. If byte use sits at 40% and inode use sits at 100%, you have found the problem in two seconds.
For counts, find with wc -l works on any directory:
$ find /var/log -xdev | wc -l
41827
The -xdev flag keeps the search on one filesystem, which stops the count from wandering into mounts. To find every path that shares a given inode number, use find -inum, which is the quickest way to locate all hard links to a file:
$ find / -xdev -inum 1310892 2>/dev/null
/home/ada/notes.txt
/home/ada/notes-copy.txt
Two situations where an inode exists but has no visible path: a file deleted while a process still holds it open, and an unlinked file held by a backup tool. lsof +L1 lists open files with a link count below one, which is how you find the process responsible before restarting it.
Why Can’t I Create a File Even When Disk Space Is Available?
Because inode capacity and byte capacity are two separate pools, and they run out independently. A filesystem formatted with a bytes-per-inode ratio of 16384 has one inode for every 16 KB of space. On a 1 TB volume that works out to roughly 67 million inodes, which sounds generous until you consider what small files do: 5 million one-byte files use about 5 MB of data and every single one of those 5 million inodes.
The count is fixed at format time. mkfs.ext4 -i 16384 or its XFS equivalent bakes the total into the filesystem structures, and it stays there. You can raise it by creating a new filesystem with a different ratio and copying the data across. What you cannot do is resize the inode count on a mounted ext4 filesystem, and any article claiming a single tune2fs flag does it is wrong. Rebuilding the filesystem is the only route, which is why the ratio deserves a decision before formatting rather than after.
The symptoms of inode exhaustion are recognisable. The most common one is the same error message a full disk produces, which sends people looking for gigabytes that do not exist:
No space left on device
Alongside that, session logins fail, cron jobs do not run, applications crash when they try to write a temporary file, databases refuse new connections, and package managers fail with errors that mention nothing about inodes at all. A failing touch on a volume with free space is the clearest single test.
| Symptom | Check | Likely cause |
|---|---|---|
| No space left on device, Use% near 100% | df -h | Byte capacity exhausted |
| No space left on device, Use% low | df -i | Inode capacity exhausted |
| Error mentions “too many open files” | ulimit -n | Descriptor limit, not inodes |
| Volume refuses writes, array healthy | Volume-level inode config | Storage array inode limit lower than the filesystem |
Container and mail workloads are the usual culprits. Each image layer, build cache and log rotation artifact is a separate file, and small-file-heavy services reach the inode ceiling long before they reach the byte ceiling. Backup trees built from hard links do the same thing at a smaller scale.
To reclaim inodes, start by finding the offender and look before you delete. find /var -xdev | wc -l per top-level directory narrows it down fast, and ls -laShr sorts a listing smallest-first, which makes short log files and cache entries obvious. Purge cache and temporary directories, rotate or truncate logs, clear the mail spool, and remove stale package-manager caches. These steps are only safe once you have listed what will match, so run the listing command first and read it.
Remember that removing a name does not always free the inode. If a process still has the file open, the inode stays allocated until that descriptor closes, which is the whole point of the lsof +L1 check.
How Inodes Behave When Files Are Deleted or Renamed
Deleting a file removes a directory entry. The filesystem decrements the inode’s link count, and if it reaches zero with no open descriptors left, the inode and its blocks are returned to the filesystem’s free pools for reuse. That is why an inode number you saw yesterday may belong to an unrelated file next month, which is also why inode numbers are never reused while the inode is still referenced.
Rename is a different operation. mv within one filesystem updates the directory entry, leaves the inode number and the link count alone, and touches the parent directory’s mtime. Across filesystems it becomes copy plus unlink, so you get a new inode. Watch for that when a log rotation script moves files onto a different mount; the inode count on the destination grows by one per file.
Open file descriptors keep an inode alive with a link count of zero. That is deliberate: a process reading a log file continues to read it even after rm, and only lsof +L1 will show you the unlinked-but-open files. Restarting the holding process is what releases them.
On recovery, be realistic. Undelete tools work by scanning for block content that still looks like the old directory entries, which depends on the filesystem, its journal and how quickly the blocks were reused. ext4 with extundelete needs an unmounted filesystem, and neither it nor photorec is guaranteed to rebuild the original names. If data matters, restore from backup rather than gambling on the inode layer.
Inodes, Blocks, and File Storage: Why They Are Not the Same
An inode is one record. A block is a fixed-size chunk of real data, typically 4 KB on ext4. The inode’s block pointers say which blocks belong to the file, using direct pointers first, then singly indirect, then doubly indirect blocks for very large files. Each level of indirection is an extra block whose only job is to hold more pointers, which is why a large file costs more blocks than its size suggests.
This is the second reason inodes and bytes fail independently. Small files are expensive in inodes and cheap in blocks. Large files are the reverse. A filesystem can therefore be completely out of inodes while holding mostly empty space, or completely out of blocks while every file is tiny.
Sparse files make the difference visible. A file created with a hole in it, or a disk image written with seek-then-write, reports a large logical size but allocates almost no blocks. ls -ls shows the allocated size in the blocks column, while du reports allocated size and du --apparent-size reports the logical size. When the two disagree sharply on a database or VM image, sparse allocation is usually the reason.
How Filesystem Type Changes Inode Behavior
Inodes are a Unix design that some filesystems adopted and others replaced with a different bookkeeping model. Commands like ls -i and stat still work across all of them, because the interface is stable even when the implementation is not.
| Filesystem | Inode model | Limit behaviour |
|---|---|---|
| ext4 | Fixed-size inode table, count set at mkfs time by bytes-per-inode | Cannot be resized on a mounted filesystem |
| XFS | Dynamic inode allocation within block groups | Grows with the filesystem rather than being pre-allocated |
| tmpfs | Inodes held in RAM, consuming memory | Limited by the tmpfs size and memory pressure |
| btrfs | No per-file inode table; metadata lives in trees with an internal identifier | No classic inode ceiling, metadata has its own allocation |
| ZFS | Object-based; inode number is synthesised from the object ID | No per-inode limit, metadata consumes pool space |
| FAT / exFAT | No inodes; flat directory entries with no metadata record | Limited by cluster count and directory entry size |
| Network filesystems (NFS, CIFS) | Inode number is a server-assigned handle | Limits and even reuse are controlled server-side |
Storage arrays add another layer. Network-attached platforms such as NetApp, TrueNAS and Synology often apply a volume-level or share-level inode limit that is lower than the underlying filesystem’s, so a volume can hit its own ceiling while df -i on the client still looks healthy. When a share refuses writes with plenty of free space, check the volume configuration rather than only the client view.
On macOS, APFS exposes inode numbers through ls -i but allocates them differently and can reuse them sooner. Windows NTFS uses a file reference structure with a sequence number that changes on reuse, so cross-platform scripts that persist inode numbers as identifiers need to account for that.
Frequently Asked Questions
What is an inode in Linux with an example?
An inode is a fixed-size record in a filesystem’s inode table holding metadata about one file or directory: type, size, owner UID, group GID, permissions, timestamps, link count and the addresses of its data blocks. Run ls -i /etc/hostname and the leading number is that file’s inode number. The filename lives in the directory, not in the inode.
What happens when inodes are full?
Creating any new file or directory fails, because the filesystem has no free inode record to assign even when bytes remain. You see No space left on device with df -h showing plenty of free space. Logins, cron jobs, package installs and application writes all start failing at once. The inode is released only when the last link is removed and no process holds the file open.
How do I check inode usage on Linux?
Use df -i to see filesystem-level totals, used inodes, free inodes and the IUse percentage. For one file, run ls -i for the number only, ls -li for number plus permissions and link count, or stat for the full field list. Use ls -lid on a directory to describe the directory itself rather than its contents, and find /path -xdev | wc -l to count entries.
How do I clean up inodes on Linux?
Find the offender before deleting anything: count entries per directory with find /var -xdev | wc -l, then sort a listing smallest-first with ls -laShr. Clear package caches, temporary directories, rotated logs and the mail spool. Check lsof +L1 for deleted files still held open by a process, since those inodes survive rm. Only reformatting raises the total inode count on ext4.
Are hard links and filenames the same as inode numbers?
No. A filename is a name stored in a directory entry, and the directory entry maps it to an inode number. Two names can point to one inode, which is exactly what a hard link is, and the inode’s link count rises to match. A symbolic link is different again: it is a separate small file with its own inode whose contents are a pathname.
Can I change inode numbers or increase inode count on a mounted filesystem?
You cannot change an existing file’s inode number; it stays with the object until the last link is removed, and a move within the same filesystem preserves it. Increasing the total inode count on ext4 means creating a new filesystem with a different bytes-per-inode ratio and copying the data across, because the count is fixed at format time. XFS and tmpfs behave differently.
Conclusion: Start by Checking the Filesystem
An inode is a metadata record, not a filename and not your data. That one distinction explains hard links, symlinks, cp versus mv behaviour, and the No space left on device error that shows up on a volume with free space to spare. Inodes explained in Linux really comes down to knowing which of two independent resource pools ran dry.
Run three checks before changing anything. Look at one file with ls -i or stat, then compare df -h with df -i on the same filesystem. If inode use is high, count entries per directory with find -xdev | wc -l and check lsof +L1 for unlinked files still held open. On ext4, remember that the inode total is fixed when the filesystem was created, so a bigger count means a new filesystem, not a flag.